AI-200 · 2.2.2 · Develop AI solutions by using Azure data management services
Vector schema design
Model schemas and implement indexing strategies, including designing tables and choosing appropriate data types
Store chunk text, metadata, and a dimensioned together; choose vector, , or sparsevec to fit the model and storage needs.
Keep chunks and metadata together
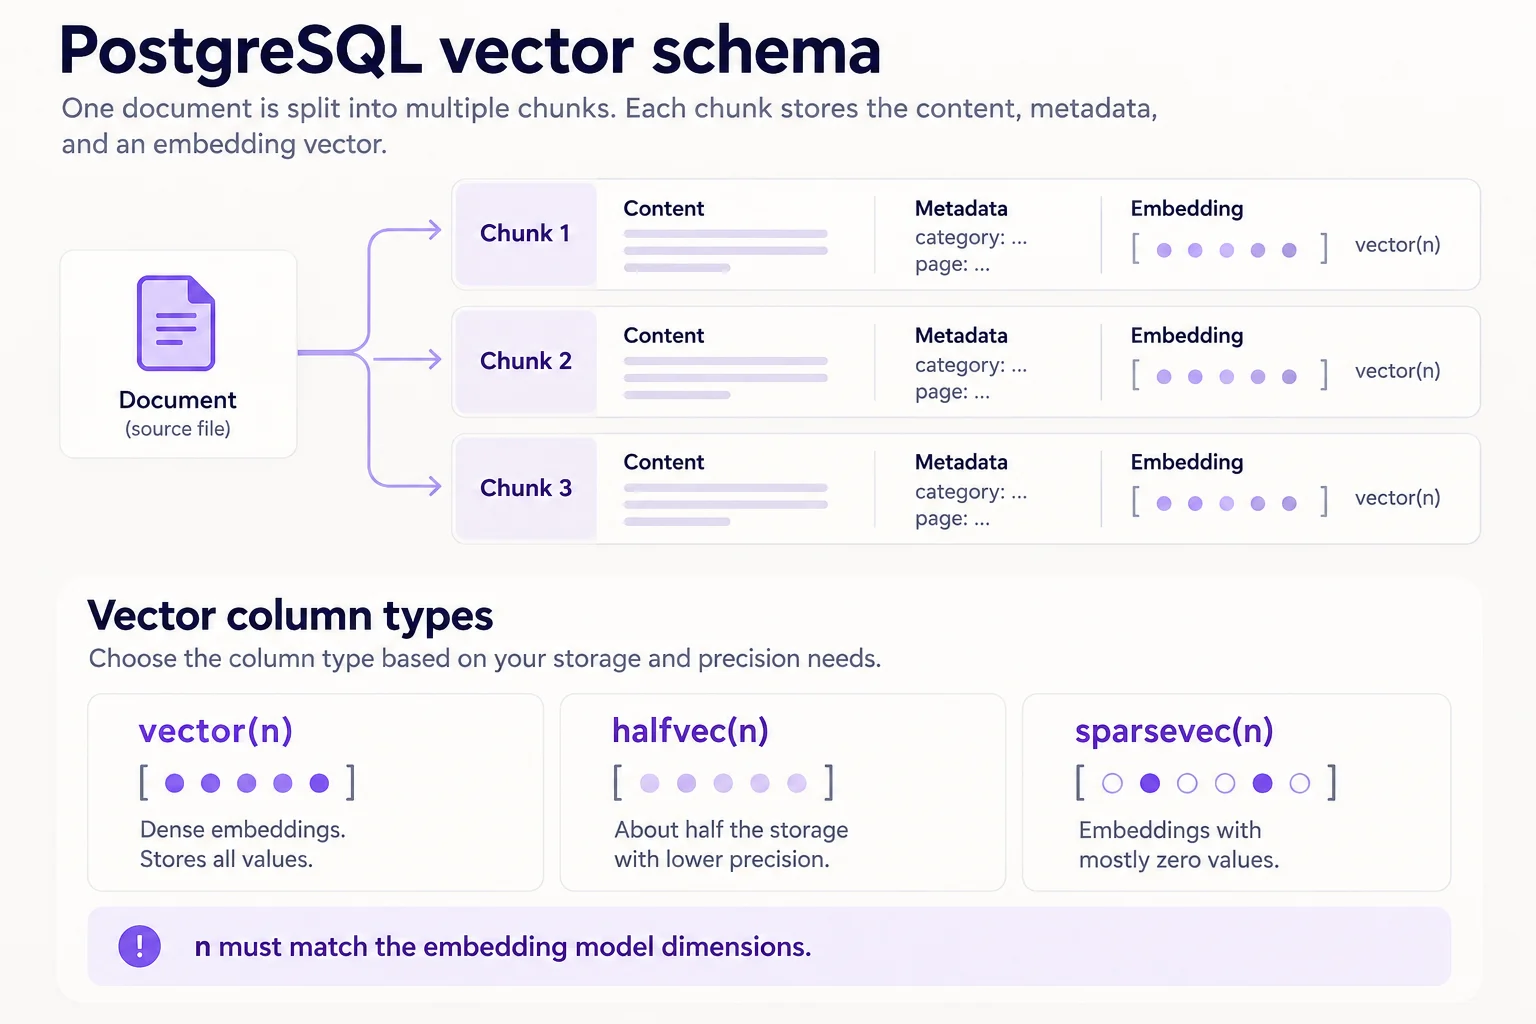
A RAG-friendly schema keeps each chunk's text, filterable metadata and in the same row, linked back to the source document. Declare the embedding as vector(n) so PostgreSQL knows its dimensions.
CREATE TABLE doc_chunks (
    id bigserial PRIMARY KEY,
    doc_id integer REFERENCES docs (id) ON DELETE CASCADE,
    content text NOT NULL,
    embedding vector(1536)
);
The dimension count must match the embedding model. A different model usually needs a new column and a backfill.
Use halfvec when lower precision is acceptable in exchange for roughly half the storage, and sparsevec for embeddings whose values are mostly zero.
Key points
- `vector(n)`: n must equal the model's number of values, or inserts fail
- Indexing: needs declared dimensions; and allow at most 2,000
- schema: documents table, chunks table, linked by a
- Switch model: add a new column, backfill it, drop the old one
Click an underlined term for a one-line explanation, or see them all in the glossary .
Exam trap
A plain `vector` column without a dimension count is accepted but cannot get an or index later; declare `vector(n)` at creation.
Sources · 3 Microsoft Learn pages Show ▾
- Store and query embeddings with pgvector (Implement vector search with Azure Database for PostgreSQL)
- Implement retrieval patterns for RAG pipelines (Implement vector search with Azure Database for PostgreSQL)
- Optimize performance when using pgvector (Azure Database for PostgreSQL)
Checked on October 4, 2026. Report a problem
Go deeper on Microsoft Learn
- Store and query embeddings with pgvector (Implement vector search with Azure Database for PostgreSQL)
- Implement retrieval patterns for RAG pipelines (Implement vector search with Azure Database for PostgreSQL)
- Optimize performance when using pgvector (Azure Database for PostgreSQL)
Checked against Microsoft Learn on October 4, 2026. Report a problem with this card