DP-750 · 4.1.6 · Deploy and maintain data pipelines and workloads
Create Lakeflow pipeline
Create a data pipeline by using Lakeflow Spark Declarative Pipelines
Declare streaming tables, materialized views, flows, and dependencies in SQL or Python, then let Lakeflow manage execution.
See the pipeline graph
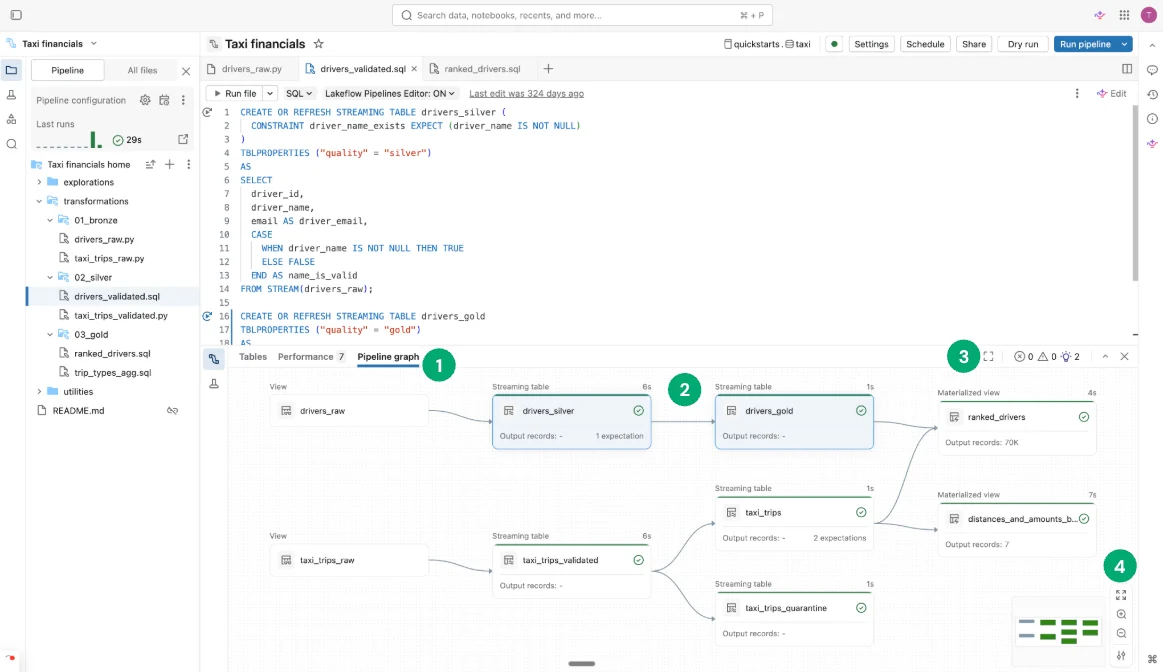
Lakeflow derives execution dependencies from dataset references. The graph makes streaming tables, materialized views, and their upstream relationships visible.
Declare datasets, not step order
- 1SourceFiles, streams, or tables
- 2BronzeRaw maintained state
- 3SilverCleansed and conformed
- 4GoldConsumption-ready output
Definitions can be written in SQL or Python. The framework manages refresh order from the data graph.
Develop in the editor
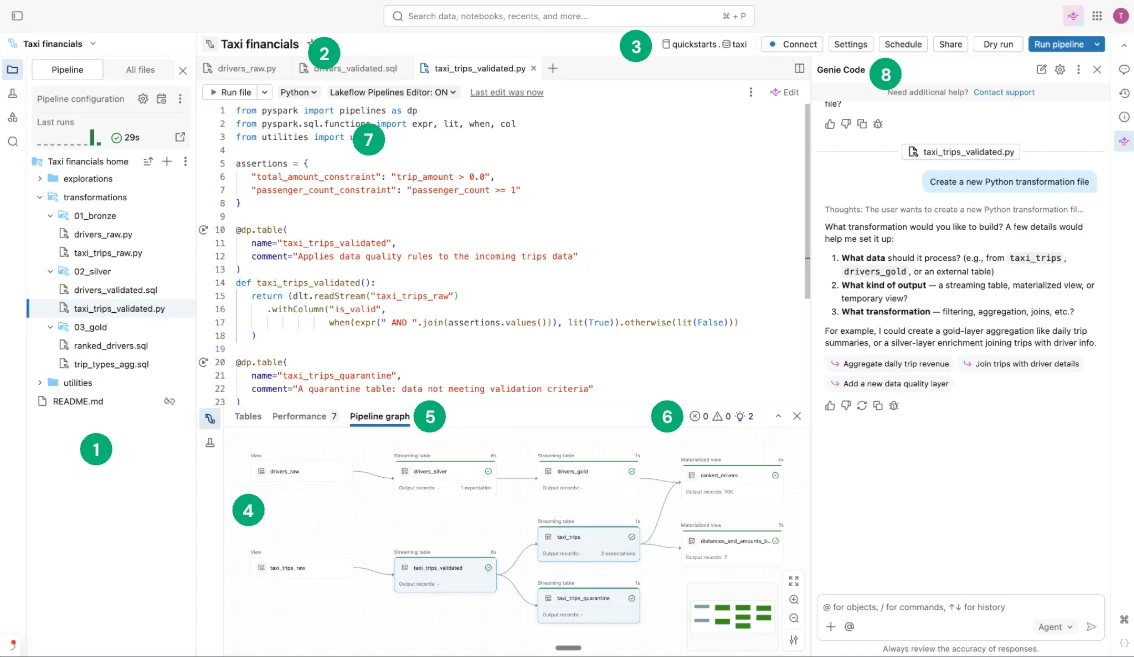
The editor supports multi-file development, dry runs, selective execution, previews, and pipeline-level monitoring.
Key points
- Dataset declaration: Defines streaming tables or materialized views
- Flow: Defines how data enters or changes a target
- Dependency graph: Inferred from dataset references
- Operations: Pipeline manages refresh, monitoring, and recovery
Exam trap
Do not manually sequence datasets whose dependencies the declarative graph can infer.
Sources · 1 Microsoft Learn page Show ▾
Checked on October 4, 2026. Report a problem
Go deeper on Microsoft Learn
Checked against Microsoft Learn on October 4, 2026. Report a problem with this card