DP-750 · 3.2.5 · Prepare and process data
Structured Streaming ingestion
Ingest data by using Spark Structured Streaming
Build fault-tolerant incremental ingestion with streaming DataFrames, checkpoints, triggers, and state controls.
See incremental ingestion as a flow
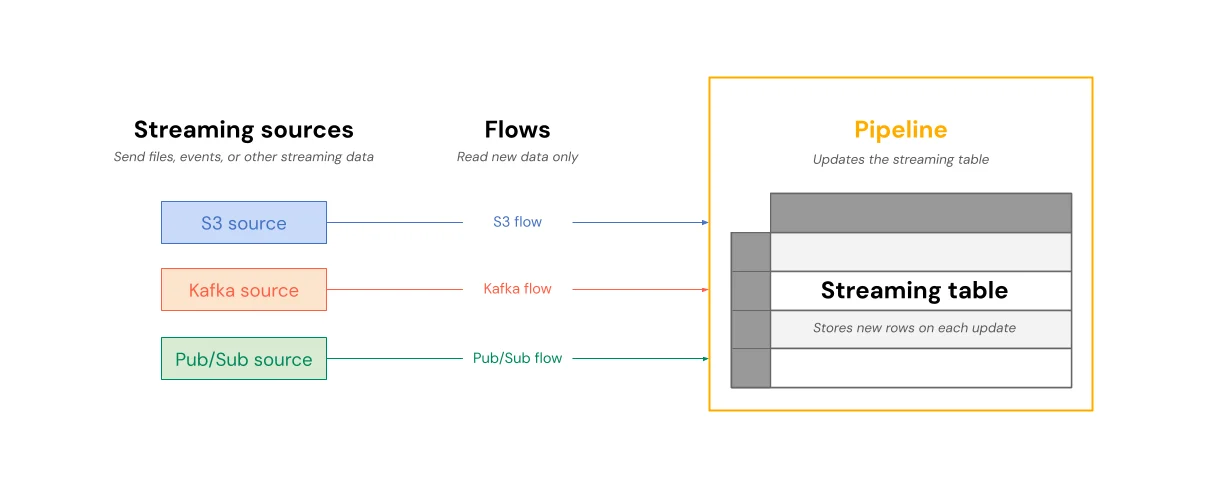
Structured Streaming continuously reads new records and updates a durable sink. The official flow anchors that mental model; the diagrams below explain checkpoints, triggers, and recovery behavior.
See the streaming lifecycle
- 1readStreamDefine the incremental source
- 2TransformApply DataFrame logic
- 3CheckpointPersist progress and state
- 4writeStreamDefine the sink and start
Structured Streaming processes unbounded data incrementally with the DataFrame API.
Recovery depends on checkpointing
- SinkReceives incremental output
- Stateful logicAggregations and joins
- CheckpointProgress, offsets, and state
- SourceContinuously arriving records
Treat the checkpoint as part of production design, not an optional convenience.
Bound late data
Watermarks define how long stateful event-time operations should retain old state for late arrivals. Use streaming when incremental freshness justifies the extra state and operational complexity.
Key points
- readStream: Defines a streaming source
- writeStream: Defines the streaming sink
- Checkpoint: Stores progress and recovery state
- Watermark: Bounds state for late event-time data
Exam trap
A streaming query without a durable checkpoint can lose reliable restart behavior.
Sources · 1 Microsoft Learn page Show ▾
Checked on October 4, 2026. Report a problem
Go deeper on Microsoft Learn
Checked against Microsoft Learn on October 4, 2026. Report a problem with this card